
p-unit
Framework for unit tests and performance benchmarks
Discover. Evaluate. Test.
LLM evaluation framework with pytest-native tests
DeepEval is an open source framework to evaluate and test LLM applications and AI agents, described as unit testing for LLMs. Test cases are written in Python and run with pytest, locally or in CI/CD pipelines, with assertions based on evaluation metrics.
It provides metrics for RAG pipelines, agents, multi-turn conversations and voice, and supports text, image and audio inputs. Custom metrics can be built from plain-English criteria (G-Eval), decision graphs or weighted scoring, using LLMs as judges. Synthetic datasets can be generated to extend test coverage.
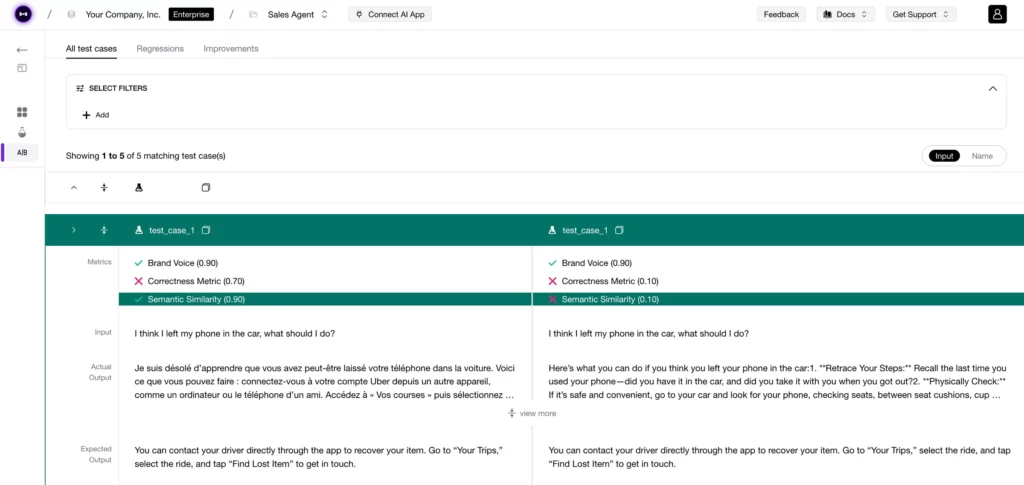
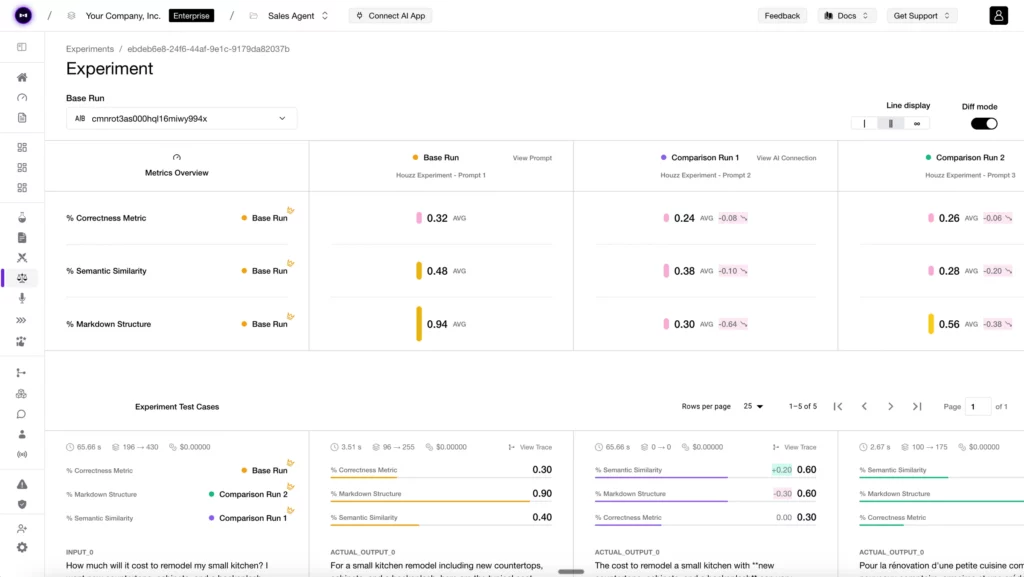
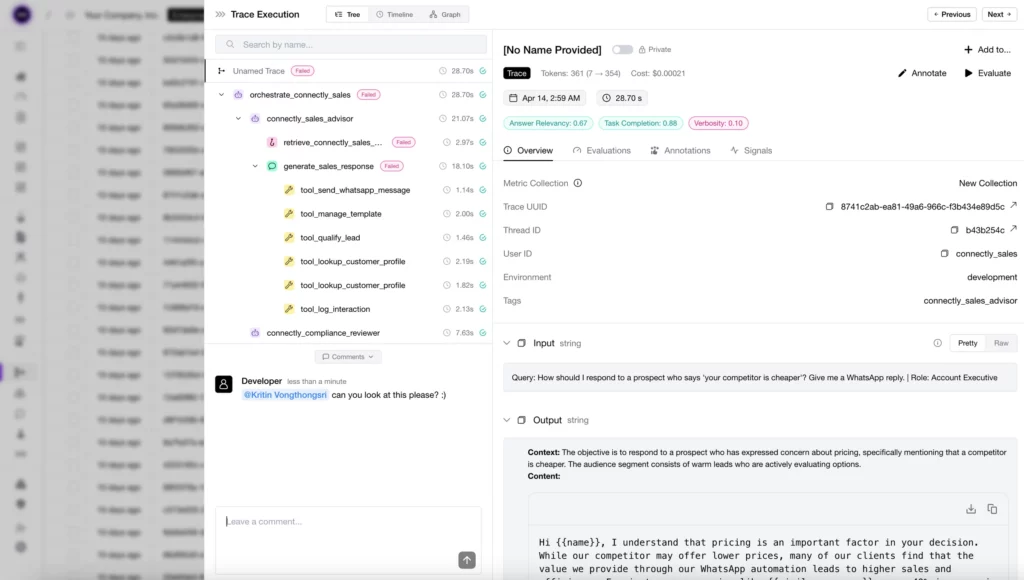
DeepEval is developed by Confident AI and is open source under the Apache 2.0 licence. The Confident AI platform, a commercial service, adds regression testing dashboards, experiment comparison, tracing, monitoring and dataset management.
There are no reviews yet.
Framework for unit tests and performance benchmarks
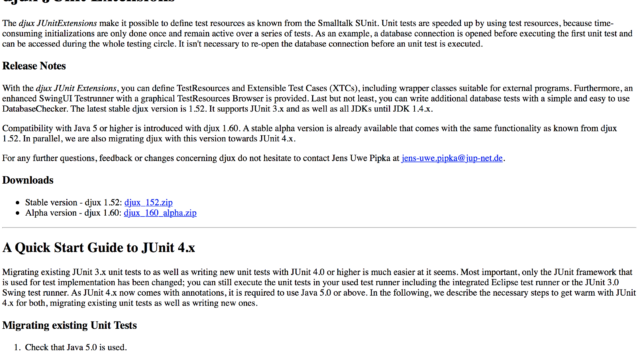
JUnit extensions adding SUnit-style test resources
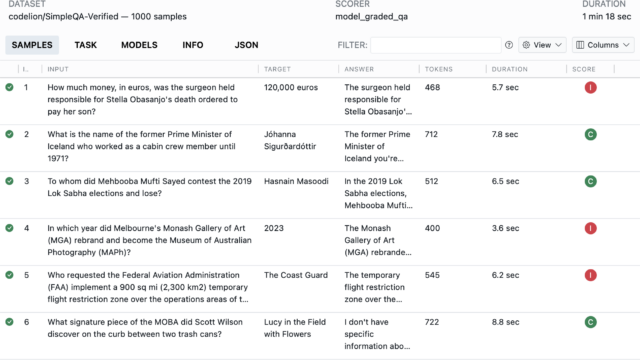
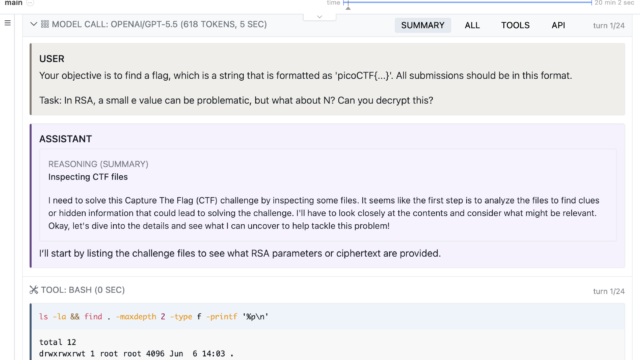
Framework for large language model evaluations
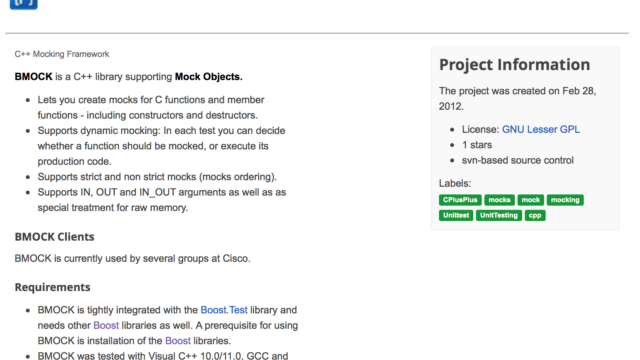
C++ mock object library for C functions and member functions
Unit testing framework for Visual FoxPro

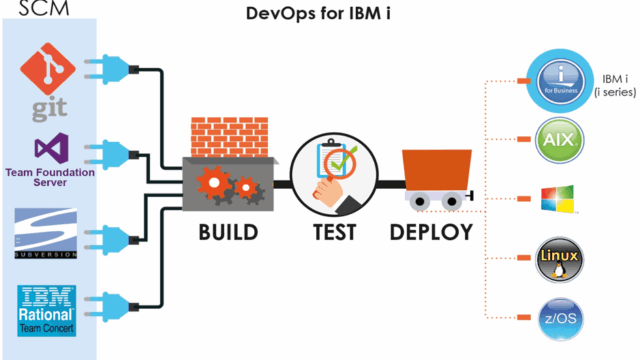
DevOps, testing and modernization tools for IBM i applications